AI directory
Foundation models, vision-language-action systems, perception stacks and the tooling behind embodied AI.
 Robot Foundation Models
Skild Brain
A robotics foundation model from Skild AI, founded in 2023 by researchers Deepak Pathak and Abhinav Gupta.
 Vision-Language-Action Models
Gemini Robotics
Brings Gemini's multimodal reasoning into the physical world through two complementary models.
 Vision-Language-Action Models
Figure Helix
A generalist vision-language-action model developed by Figure AI to control its humanoid robots, using a decoupled dual-system architecture.
 Vision-Language-Action Models
NVIDIA Isaac GR00T
NVIDIA's open VLA family for humanoid robots, first announced at GTC 2025.
 Robot Foundation Models
Octo
A transformer-based diffusion policy pre-trained on 800,000 robot episodes from the Open X-Embodiment dataset.
 Vision-Language-Action Models
Google RT-2
Published by Google DeepMind in July 2023, widely credited as the first model to establish the vision-language-action concept.
 Robot Foundation Models
Physical Intelligence π0.5
Keeps the π0 recipe — a vision-language-model backbone with a flow-matching action expert — but is built around generalization to new environments.
 Motion Planning & Control
ROS 2 (Robot Operating System)
An open-source middleware framework for building robot software, maintained by Open Robotics.
 Vision & Perception AI
OpenCV
A foundational dependency in essentially every robotics vision pipeline built over the last two decades.
 Teleoperation & Data Collection Tools
Meta Aria Research Kit
Meta Reality Labs Research's egocentric multimodal sensing platform, worn like ordinary glasses.
 Teleoperation & Data Collection Tools
ALOHA + Mobile ALOHA
An open-source data-collection platform for bimanual teleoperation, and its mobile successor.
 Multimodal LLMs for Embodied AI
Claude Opus 4.6
Anthropic's high-end multimodal large language model in the Claude 4.x family, designed to balance frontier reasoning with practical deployment.
 Multimodal LLMs for Embodied AI
Gemini 2.5 Pro
Google DeepMind's flagship multimodal model with a 1M-token context window (2M coming) and native vision, audio, and video understanding. Strong reasoning and code generation. Used in robotics — including Gemini Robotics — for embodied reasoning and long-horizon planning.
 Multimodal LLMs for Embodied AI
GPT-4o (OpenAI)
<span data-contrast="auto">GPT-4o ('Omni') allows robots to see, hear, and speak in real-time. It acts as the high-level reasoning layer for mission planning and human interaction.</span><span data-ccp-props="{"201341983":0,"335559739":160,"335559740":278}"> </span>
 Vision & Perception AI
ORB-SLAM3
Open-source feature-based SLAM library from University of Zaragoza. First system to perform visual, visual-inertial, and multi-map SLAM with monocular, stereo, RGB-D, and fisheye cameras. Reports 3.6 cm accuracy on EuRoC and 9 mm under quick hand-held motion on TUM-VI.
 Speech & Dialogue for Droids
Piper TTS
Fast, local neural text-to-speech engine optimised for Raspberry Pi 4/5 and similar low-power hardware. ONNX-based, real-time, and used in Home Assistant Voice. Voices range ~20-100 MB and run on CPU only.
 Speech & Dialogue for Droids
OpenAI Whisper (local)
Open-source automatic speech recognition model from OpenAI. Trained on 680,000+ hours of multilingual audio (5M+ for large-v3); six model sizes from ~39M tiny to 1.55B large. Runs fully offline via whisper.cpp, faster-whisper, or WhisperKit — robust to accents, noise, and 100+ languages.
 Edge AI Hardware for Droids
Hailo
Israeli edge-AI silicon company producing low-power neural processing units. Hailo-8 delivers 26 TOPS at ~2.5 W; new Hailo-10H delivers 40 INT4 TOPS at 2.5 W and supports on-device LLMs and VLMs up to ~1.5B parameters, including via the Raspberry Pi AI HAT+.
 Edge AI Hardware for Droids
NVIDIA Jetson
Family of embedded AI computing modules (Orin Nano, Orin NX, AGX Orin, AGX Thor) running deep-learning inference on robots. Top-end AGX Orin delivers 275 TOPS of AI performance at 15-60 W; the de-facto standard for on-board AI in commercial robotics.
 Simulation Platforms
Genesis
Family of embedded AI computing modules (Orin Nano, Orin NX, AGX Orin, AGX Thor) running deep-learning inference on robots. Top-end AGX Orin delivers 275 TOPS of AI performance at 15-60 W; the de-facto standard for on-board AI in commercial robotics.
 Robot Foundation Models
Figure Helix
End-to-end vision-language-action model from Figure that runs entirely on the Figure 02 and Figure 03 humanoids. A dual-system architecture (System 2 ~7B VLM for reasoning, System 1 ~80M transformer for fast control) enables 35-DoF whole-upper-body control. Helix 02 (Jan 2026) extends to whole-body autonomy.
 Robot Foundation Models
Google RT-2
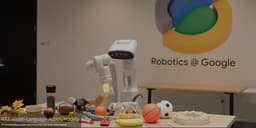
Vision-language-action model from Google DeepMind that co-fine-tunes large web-scale VLMs (PaLI-X, PaLM-E) with robot trajectory data. Robot actions are encoded as text tokens, allowing the model to inherit chain-of-thought reasoning and generalise to novel objects and instructions seen only on the internet.
 Simulation Platforms
MuJoCo
Open-source physics engine ('Multi-Joint dynamics with Contact') maintained by Google DeepMind. Provides fast, accurate simulation of articulated robots and contact dynamics in generalised coordinates. The standard engine for reinforcement-learning research in locomotion and manipulation.
 Simulation Platforms
NVIDIA Isaac Sim
Open-source GPU-accelerated robotics simulation framework built on NVIDIA Omniverse and OpenUSD. Provides photorealistic ray-traced environments, PhysX-based physics, multi-sensor simulation, synthetic data generation via Replicator, and Isaac Lab for reinforcement-learning-based robot training.
 Vision-Language-Action Models
Physical Intelligence π0
General-purpose ~3.3B-parameter Vision-Language-Action flow-matching model from Physical Intelligence, built on a PaliGemma VLM backbone. Outputs continuous action chunks at up to 50 Hz, enabling dexterous manipulation across many robot embodiments.
 Vision-Language-Action Models
OpenVLA
Open-source 7B-parameter vision-language-action model trained on 970,000 real-world robot demonstrations. Built on a Llama 2 backbone with a fused DINOv2 + SigLIP vision encoder. Generalises across multiple robot embodiments and supports parameter-efficient fine-tuning for new robots.
 Multimodal LLMs for Embodied AI
Qwen-VL
Open-weights multimodal LLM family from Alibaba. Latest Qwen3-VL ships in Dense and Mixture-of-Experts architectures from edge to cloud; Qwen2.5-VL covers 3B / 7B / 32B / 72B sizes. Strong vision, video understanding (>1 hour), and bilingual Chinese/English text recognition.
Let's get in touch with us
At the intersection of innovation and technology, we are pioneers crafting a landscape for the digital age.