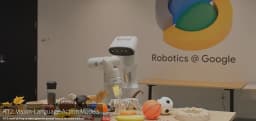
RT-2 showed that a vision-language model trained on web-scale image and text data could be fine-tuned to output robot actions directly, inheriting some of the web model's semantic reasoning in the process. Much of the VLA research that followed — including several other entries in this directory — traces its lineage back to this paper.
More in Vision-Language-Action Models

Gemini Robotics
Brings Gemini's multimodal reasoning into the physical world through two complementary models.

Figure Helix
A generalist vision-language-action model developed by Figure AI to control its humanoid robots, using a decoupled dual-system architecture.

NVIDIA Isaac GR00T
NVIDIA's open VLA family for humanoid robots, first announced at GTC 2025.
Let's get in touch with us
At the intersection of innovation and technology, we are pioneers crafting a landscape for the digital age.